Start with a bounded question
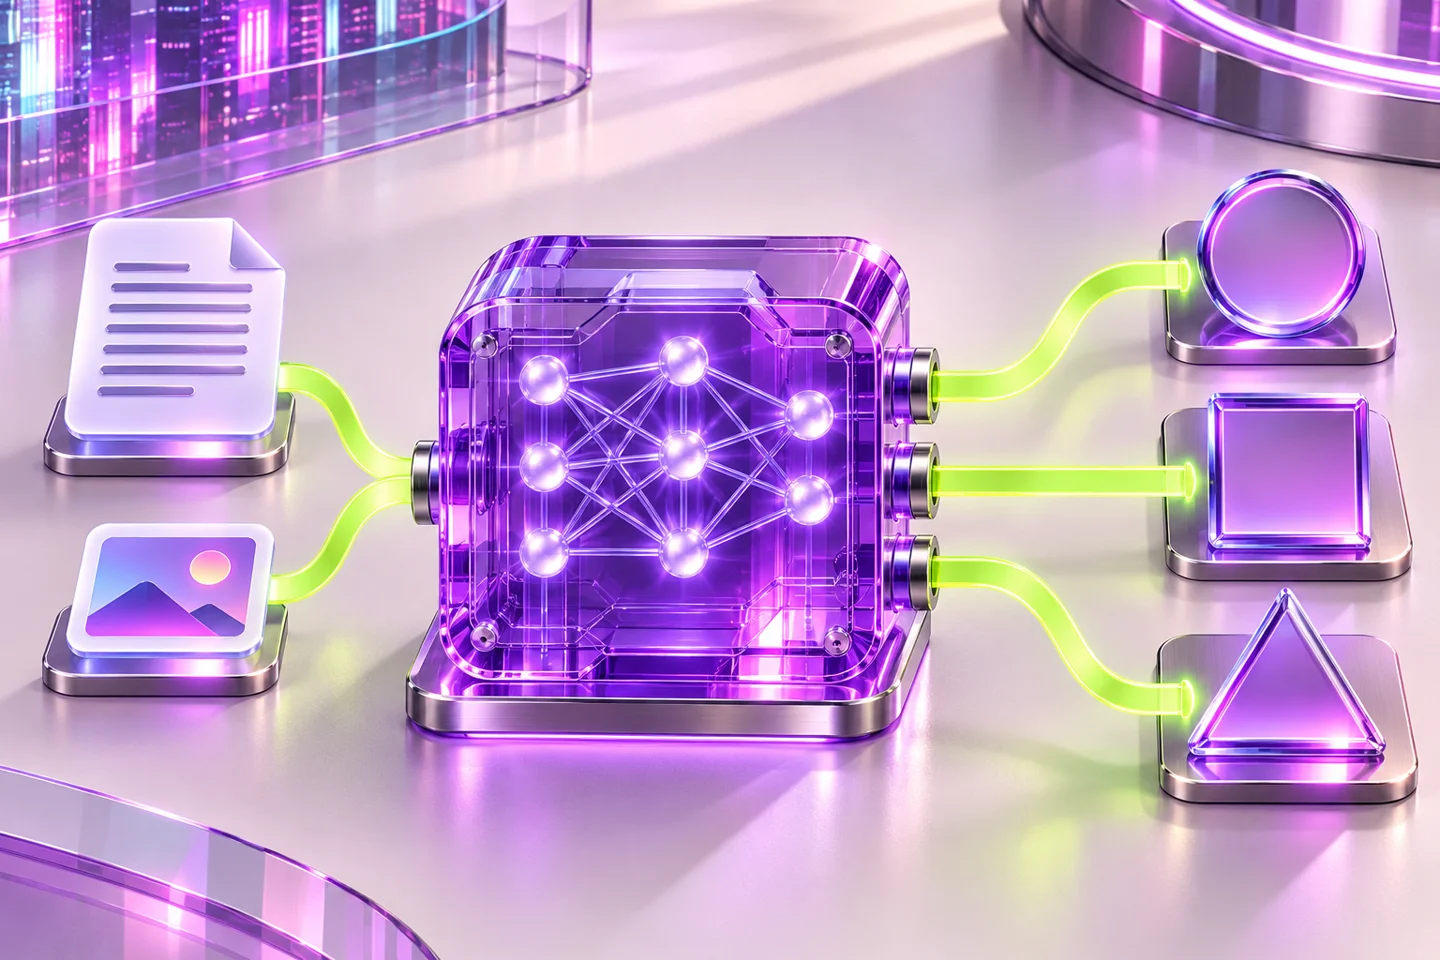
The documented use cases include routing requests, checking conditions and evaluating document fields. Inputs can include text and images. The integration begins by defining the question and its allowed outcomes rather than asking for an unrestricted conversational response. A bounded output space can make an answer easier for application code to consume. It does not establish that the selected answer is correct: semantic mistakes remain possible even when a result follows the required schema perfectly. Reliable structure and reliable judgment therefore need separate evaluation.
Distinguish adaptation methods
A system instruction describes desired behavior at inference time. A skill can supply instructions and a workflow, while fine-tuning changes model parameters using training examples. Clef is an example of the latter kind of specialization, rather than simply a published prompt template. Our assessment is that teams searching for model competencies should first identify which layer needs adaptation. Some tasks need a clearer output schema; others need retrieved information, additional tools or a trained adapter. Selecting an adaptation technique before defining the failure being addressed makes it harder to judge whether the extra complexity is justified.
Scores need task-level validation
Candidate probabilities can support thresholds and review queues, but they are not guarantees of factual truth. Evaluate them on labeled examples separate from training data, including ambiguous inputs and cases outside the intended distribution. False positives and false negatives may have different operational costs. Benchmark comparisons in the announcement belong to the model authors; they should not be generalized to every production workflow. A more useful criterion is the quality and error cost on the application’s actual data, compared with a simple rule or a baseline model under the same acceptance criteria.
Separate local and cloud operation
Local availability and cloud availability imply different resource requirements, latency and data routes. A catalogue entry does not mean that a model fits every laptop, and a cloud request does not stay on the device merely because the client is Ollama. Begin with one narrow workflow and establish whether specialized decisions improve its outcome. Only then expand the automation or connect consequential external actions. This makes the benefit of specialization measurable and keeps the choice of runtime, model, instructions and operational permissions tied to the task being solved.