
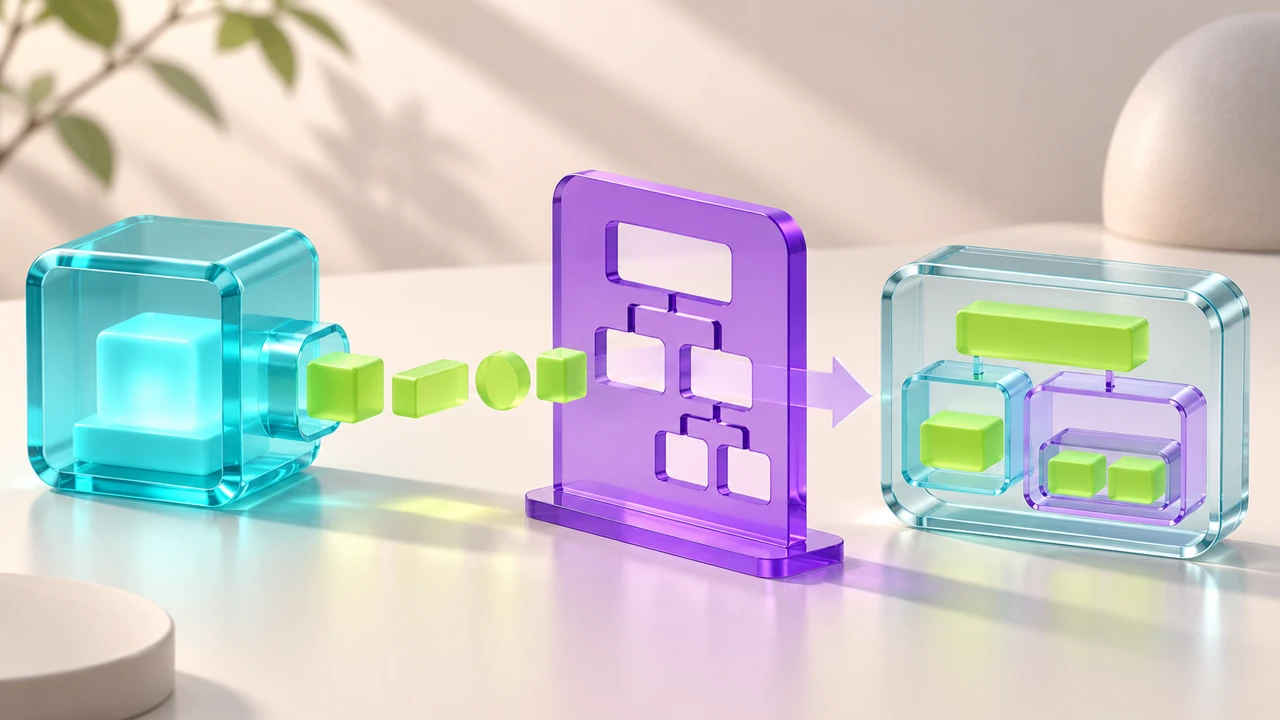
Why the old trigger could miss the call
The original issue describes llama-server on Linux, build 12492, using a Llama 3.2 1B Instruct GGUF and the Jinja template. It contrasts unconstrained auto-mode output with constrained output when tool selection is required.
That comparison is useful because it separates the choice of whether to call a tool from the syntax of the call itself. Our reading is that changing a model’s size or quantization would not directly explain a runtime path that fails to create its grammar.
The change recognizes a JSON opening
The PR explains that some Llama 3.x templates emit a plain object with a top-level name field and no preceding marker. In that case, the parser now uses a pattern on the object’s opening to trigger lazy grammar.
The conditions matter: the described fallback is for the plain-object shape, rather than every possible tool serialization. A schema with the function name as a key or an outer array is not automatically covered by this particular explanation. Our conclusion is to identify the actual chat template before attributing an observed change to the patch.
Tests cover grammar creation, not every agent outcome
The contributor added Llama 3.2 template tests with and without whitespace and reports test-chat passing. The PR also discloses AI assistance with its code and supporting material. These are project records; we did not run the tests independently.
A useful application check would distinguish valid JSON, conformity with the tool schema and correctness of the requested operation. Those are separate questions. A syntactically valid object can still contain the wrong argument, reference unavailable data or select an unsuitable action.
Formatting is only one boundary in tool use
The release and merged PR describe one runtime fix. The November 17 bug report is earlier evidence, rather than a separate launch; the date of the merged correction is November 22. No new model license or hardware requirement is established by this change.
Our assessment is that local agent developers should evaluate output formatting alongside their existing argument validation and action controls. Grammar can constrain the representation of a call; it cannot by itself provide authorization or verify the real-world result. We have not installed a model, executed a tool call or changed a running agent’s permissions.
Discussion.
Your perspective matters. Sign in, pick a nickname and choose your cyber identity.
Loading discussion…
Your account name, email and photo stay off your comments.