
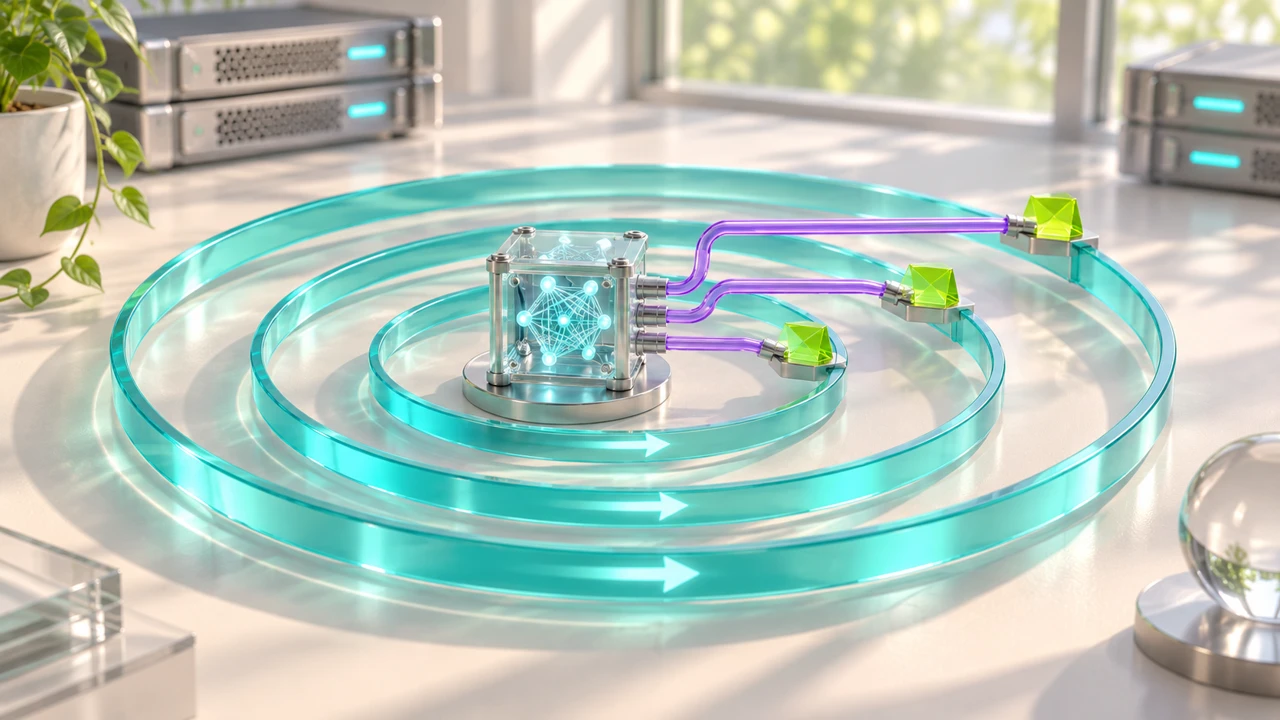
The problem was the order of loading operations
The release describes loop slots being copied at the end of load_arch_tensors. A later generic pass attached optional scale tensors to the physical layers, but the previously shared slots did not acquire that information. Later passes through the core therefore lacked the scales needed for those NVFP4 experts.
The correction adds an optional post_arch_tensors hook and shares the slots after the scale pass. In practical terms, reusing a layer also has to reuse the complete data needed to interpret its weights. Sharing a reference at the wrong stage can produce an incorrect calculation even when the file loads.
The review separates affected and unaffected files
In the pull request, contributor Daniel Han describes the issue for scaled NVFP4 files and explicitly distinguishes ordinary ggml quantizations. Later review comments compare a ggml-org IQ4_NL file before and after the change and report the same result. Those are contributor checks, not measurements conducted by this publication.
The distinction prevents a misleading conclusion that every Inkling quantization was broken or that every file becomes better after updating. A model name alone does not identify the representation and loading path that a deployment actually uses.
A merged repair is not a universal deployment guarantee
The official pull request is merged, and the b12611 release records the same change. Third-party comments and integrations can describe an earlier unmerged snapshot; the official merge and release are the evidence used here to establish availability.
The discussion also contains separate user reports concerning memory use and backend behaviour. This scale-sharing repair does not establish that those problems are solved. It is neither a memory-capacity promise nor a new throughput benchmark.
How this changes evaluation of a local setup
Our operational interpretation is to record the exact runtime build and weight file when comparing results. Keep the prompt, template and backend settings consistent, and check correctness alongside memory use and generation speed. A failed test on an older loader should not automatically be attributed to the model itself.
The event covered here is the November 21 scale-handling repair. We have not installed the model or run its code, and we do not infer new licensing, training capabilities or hardware support from this patch. The release and its pull request remain one event rather than duplicate articles.
Discussion.
Your perspective matters. Sign in, pick a nickname and choose your cyber identity.
Loading discussion…
Your account name, email and photo stay off your comments.