
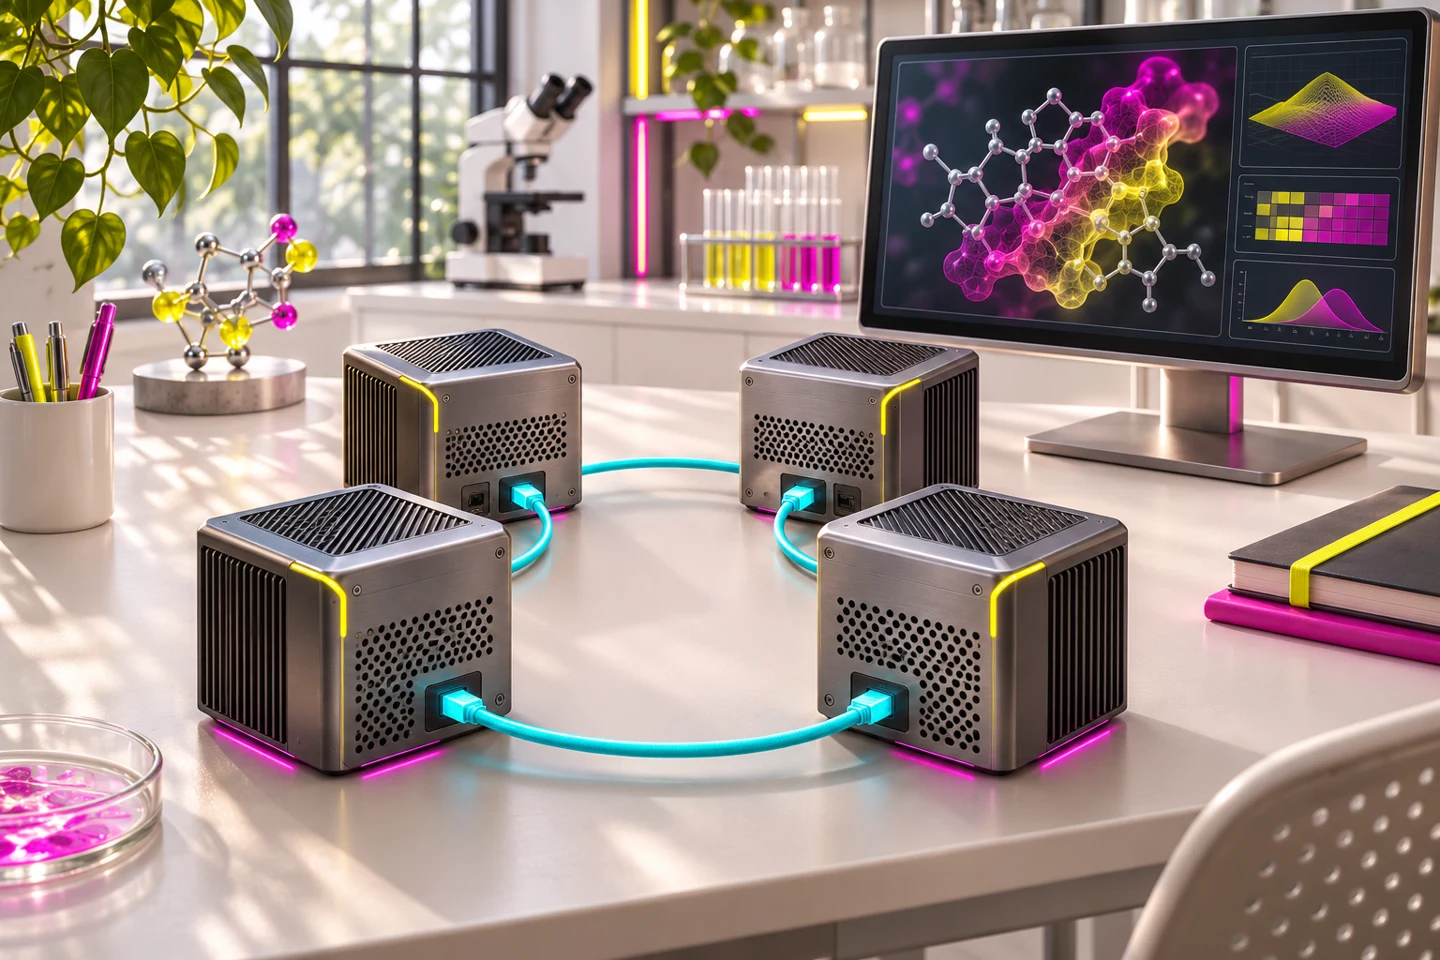
Four connected systems still require distributed software
Each system uses the GB10 Grace Blackwell Superchip. Direct connections to neighboring nodes remove the external switch from the topology described in the announcement. Combined memory should not automatically be interpreted as the local memory of a single GPU: an application must distribute its work and exchange data between systems. NVIDIA says four nodes can deploy models of up to 700 billion parameters using NVFP4. That is a capacity claim under a specified precision format, rather than a promise of arbitrary context length or uniform performance across every large model.
Scientific development is a different workload from chat inference
The company lists LAMMPS with Kokkos and NAMD among demonstrated four-system workloads. It separately describes community-validated examples involving GROMACS, OpenFOAM and WRF. These examples do not constitute one standardized benchmark result for every application in the kit. A research team may value the local cluster for testing data distribution, debugging communication and preparing simulations before consuming time on a larger shared machine. Those are different measures of usefulness from the highest tokens-per-second rate achieved by a conversational model.
Adapter examples and avoided queue time need careful interpretation
The announcement describes the Hartwig Group at Berkeley using a single DGX Spark for LoRA fine-tuning of Nemotron 3 Super 120B-A12B in chemistry machine learning with NVFP4. Other reported research examples avoid multi-hour or multi-day waits for shared cluster allocations. Receiving results sooner because there is no queue is not the same as accelerating the underlying computational kernel by that factor. Applicability depends on the model, adapter, numerical format and task. The case study should not be generalized into a claim that arbitrary full training of large models fits or runs quickly on one desktop system.
Hardware availability and the software playbook have different timelines
NVIDIA says the kit is displayed at SC26 and available for sale, with systems and cables offered through OEM partners and NVIDIA Marketplace. The dedicated NVIDIA HPC SDK installation playbook is still coming. That guide is intended to cover GPU-accelerated C, C++ and Fortran compilers, libraries and message-passing tools. A team planning a local test environment should distinguish hardware availability from the readiness of that particular deployment guide. Code compatibility, communication topology, numerical precision and measurements of the actual workload remain central to a useful evaluation.
Discussion.
Your perspective matters. Sign in, pick a nickname and choose your cyber identity.
Loading discussion…
Your account name, email and photo stay off your comments.